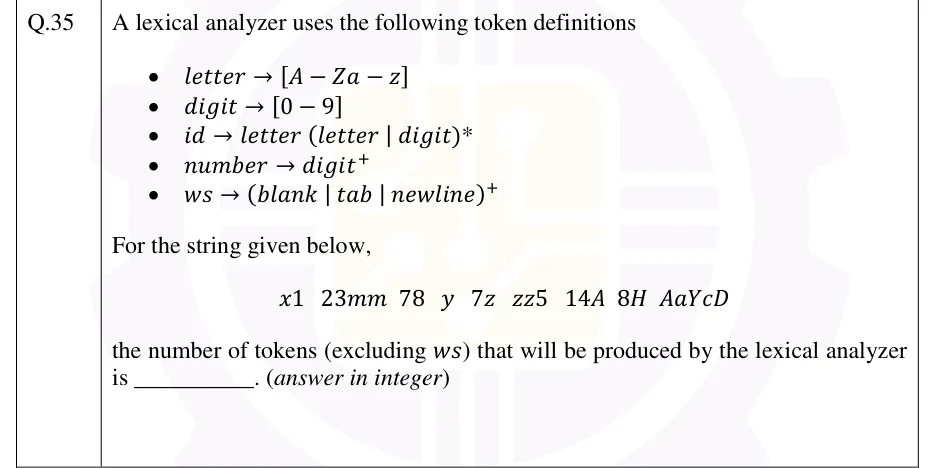
A lexical analyzer uses the following token definitions
For the string given below,
x1 23mm 78 y 7z zz5 14A 8H AaYcD
the number of tokens (excluding ) that will be produced by the lexical analyzer is ______. (answer in integer)

A lexical analyzer uses the following token definitions
For the string given below,
x1 23mm 78 y 7z zz5 14A 8H AaYcD
the number of tokens (excluding ) that will be produced by the lexical analyzer is ______. (answer in integer)
ANSWER
The lexical analyzer produces 13 tokens, excluding white space.
Official answer: 13Source: Official answer key, GATE 2026 CS2 (IIT Guwahati)
The analyzer always takes the longest match from the current position. An must start with a letter and may then continue with letters or digits. A is a run of digits only.
White space is skipped, because is excluded from the count. Split the string at the blanks: x1, 23mm, 78, y, 7z, zz5, 14A, 8H, AaYcD.
x1 begins with a letter, so the whole of it is one . Tokens: 1.
23mm begins with a digit, so it cannot be an . The longest is 23, because m is not a digit. Then mm is one . Tokens: 2.
78 is one . Tokens: 1.
y is one . Tokens: 1.
7z: the longest is 7, then z is an . Tokens: 2.
zz5 begins with a letter, and a digit may follow inside an , so it is one . Tokens: 1.
14A: 14 is a , then A is an . Tokens: 2.
8H: 8 is a , then H is an . Tokens: 2.
AaYcD is all letters, so it is one . Tokens: 1.
Total: .
KEY IDEA
A lexer takes the longest match at each position. An identifier must start with a letter, while a number is digits only, so a lexeme that starts with a digit splits where the digits end.
WATCH OUT FOR
Treating a lexeme such as 23mm or 7z as a single token. An cannot start with a digit, so each of these splits into a followed by an . Another slip is splitting zz5 into two tokens, when a digit is allowed inside an after its first letter.
From the GATE 2026 CS2 paper. Every question of this paper · Download the full paper · All 8 Lexical analysis questions, with notes